Why Does AI Give a Different Answer to the Same Question?
Why AI answers vary on repeat questions, and four ways to measure it that still mean something.
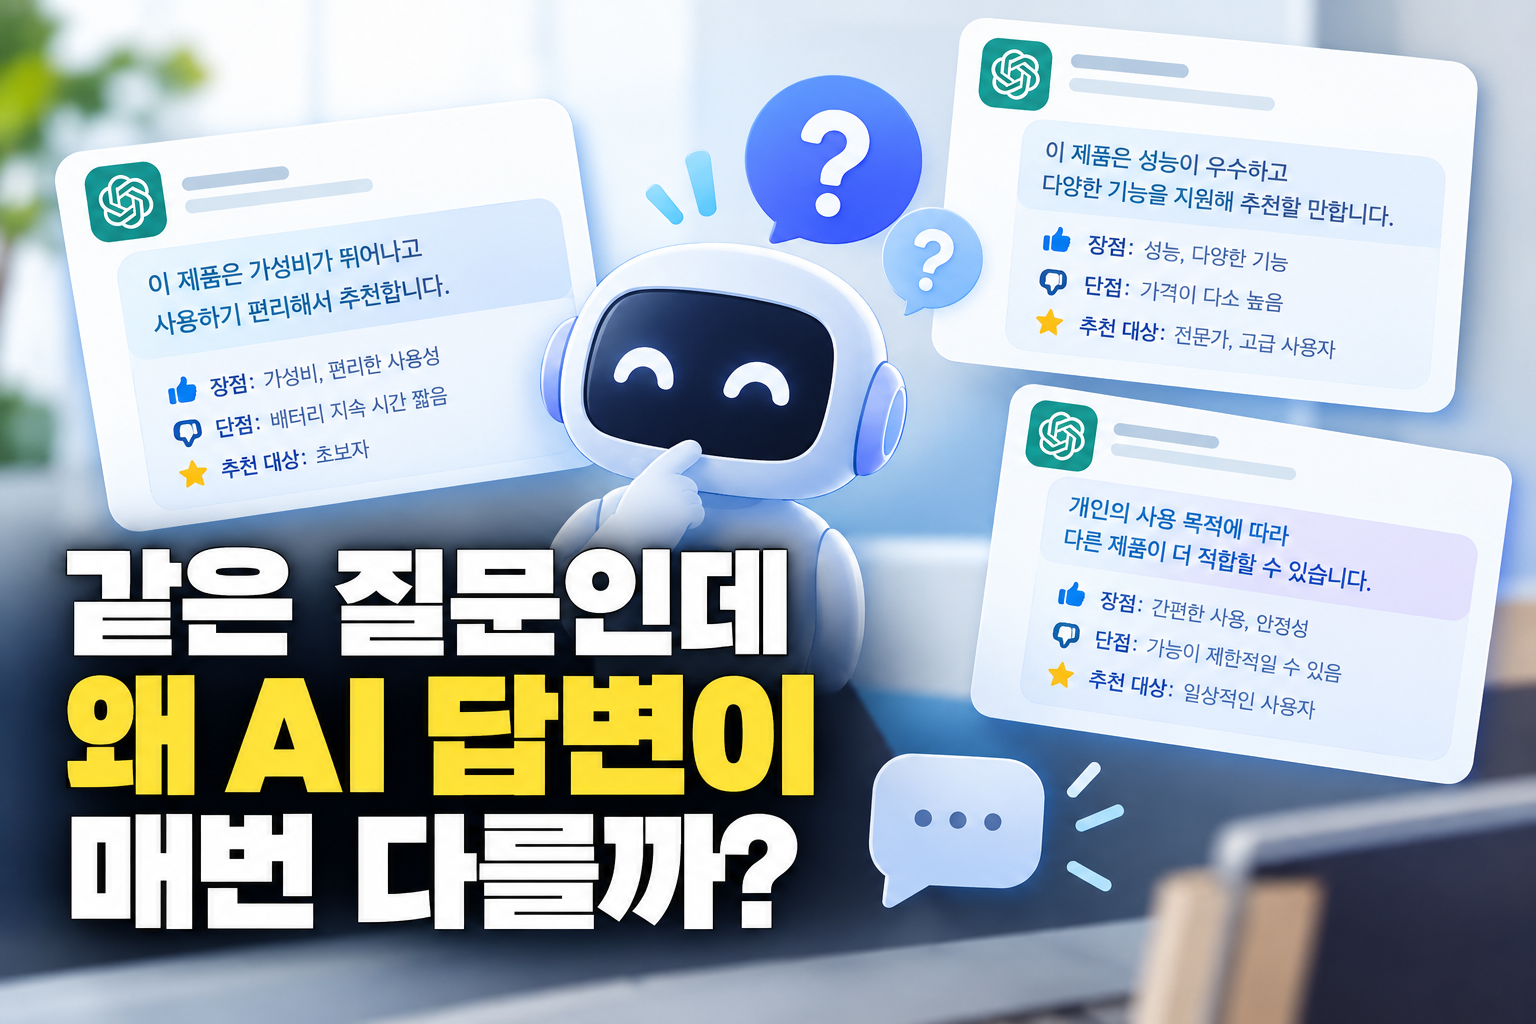
If you asked the same question again and got a different answer, the measurement isn't broken: that's just how it works. Don't decide you show up or don't based on a single result; repeat the same question several times and look at the rate instead. This piece covers why the answer changes every time, and how to measure it meaningfully despite that variation.
Why the answer changes every time
Generative AI picks the next word probabilistically every time it builds an answer. The value that controls this probabilistic choice is usually called temperature, and whenever it's set above zero, both word choice and the entire sentence can change from one run to the next for the same question. Commercial chat AI services are generally run with this value above zero, so getting the exact same sentence twice for the same question is rare.
This probabilistic choice also directly affects which brand gets mentioned first in an answer, and how many get mentioned at all. If a different word gets picked in the first sentence, everything that follows changes too, and a specific brand can end up mentioned or left out along the way.
On top of that, whether you're logged in, where you're connecting from, and when you ask all affect which underlying search results the model draws on. If a logged-in account's past conversation history or location data feeds into the search results, different people can get different answers to the identical question.
Separate from variation within one service, there's also variation between services like ChatGPT, Gemini, and Perplexity. Each builds its answer from a different model and different search results, so a rate measured on one service doesn't carry over to another. That's why your tracking sheet needs to record which engine each number came from.
Why you can't conclude anything from a single query
That's why "I asked today and we showed up" or "we didn't show up" isn't, by itself, solid evidence either way. You need to look at the rate at which a brand appears across 5 or 10 repetitions before any real pattern emerges.
Showing up once out of five tries and showing up four times out of five are both technically "it showed up," but they mean very different things. One is 20%, the other is 80%, and a single answer screen can't tell you which one you're looking at.
Mistaking one lucky (or unlucky) result for the overall trend can lead you to believe you show up constantly when you barely do, or the reverse. Running more repetitions isn't really about precision; it's closer to earning the right to draw any conclusion at all.
How to make repeated measurement actually mean something
First, repeat the same question at least 5 times and look at the rate, not a single outcome. Record how many of the five times it showed up, not just whether it did once.
Second, open a fresh session each time while logged out: an incognito window or temporary chat works. Staying logged in, or carrying over prior conversation history, can skew the answer toward what that account has seen before.
Third, keep the question's wording exactly the same. AI breaks sentences into small units for processing, so even changing a single particle or word order can be read as an entirely different input and shift the results. Copying the exact wording from your first run into every later run is the safest approach.
Fourth, record the exact date, time, and wording you used for each run. That's what lets you make a fair comparison the next time you measure the same question.
What to put in your tracking sheet
Once you've asked a question five times, keep the results in a table. Fill in the columns below, one row per run.
| Column | What to record |
|---|---|
| Date | Date and time of day |
| Engine | Name of the service |
| Question | Exact wording, copied and pasted |
| Run | Which of the five runs |
| Appeared | Whether your company showed up, and where in the answer |
| Co-mentioned | Other names listed alongside yours |
Keeping a table turns "how many out of five" into an actual number, so the next time you measure under the same conditions, you can line up the two points directly. Saving a screenshot of each run also lets you go back and check exactly what the answer said.
Don't stop at the rate alone. Check the co-mentioned column too. If the same handful of names keep showing up alongside yours across all five runs, the table shows you exactly who you're being compared against in that answer. Appearing and being co-mentioned move independently, so you need both to see the full picture.
Common mistakes to avoid
Concluding you do or don't show up from a single answer screen is the most common mistake. One screen is just one out of five runs, and there's no guarantee that one run represents the whole.
Changing the question's wording slightly between runs is another one to avoid. Polishing the phrasing each time to sound more natural effectively asks a different question each time, making it impossible to tell whether a difference between runs came from the question or from the AI's own variation.
Repeating the question while logged into your everyday work account is also a problem. That account's accumulated conversation history and location data bleed into the answer, producing a different result than what someone else asking the identical question would see.
Asking the AI to rank vendors and then using that score as a measurement is something to avoid as well. That kind of question doesn't resemble what a real user would actually ask, and the ranking it produces is generated on the spot rather than a rate derived from repeated measurement.
Tracking change over time
Measuring once and stopping isn't enough. Repeating the same method on a regular schedule lets you see whether the rate is climbing or falling, which is a far more meaningful signal than the one-day worry of "it showed up yesterday but not today."
A one- to two-week interval between measurements works well. Measuring too often makes it hard to separate normal run-to-run variation from an actual trend. Measuring too rarely makes it hard to pin down what caused the rate to change in between.
The record itself becomes an asset the more often you measure. A trend spanning several months is a far more convincing basis than any single measurement.
The specific steps for repeated measurement, asking a question five times per engine and tracking it in a table, are laid out here. See the full walkthrough